- Services
Every open model in our directory, ranked by how well it runs on MINIX T5000 (128GB) at 4-bit. Grades weigh whether the model fits in memory and how fast it should run.
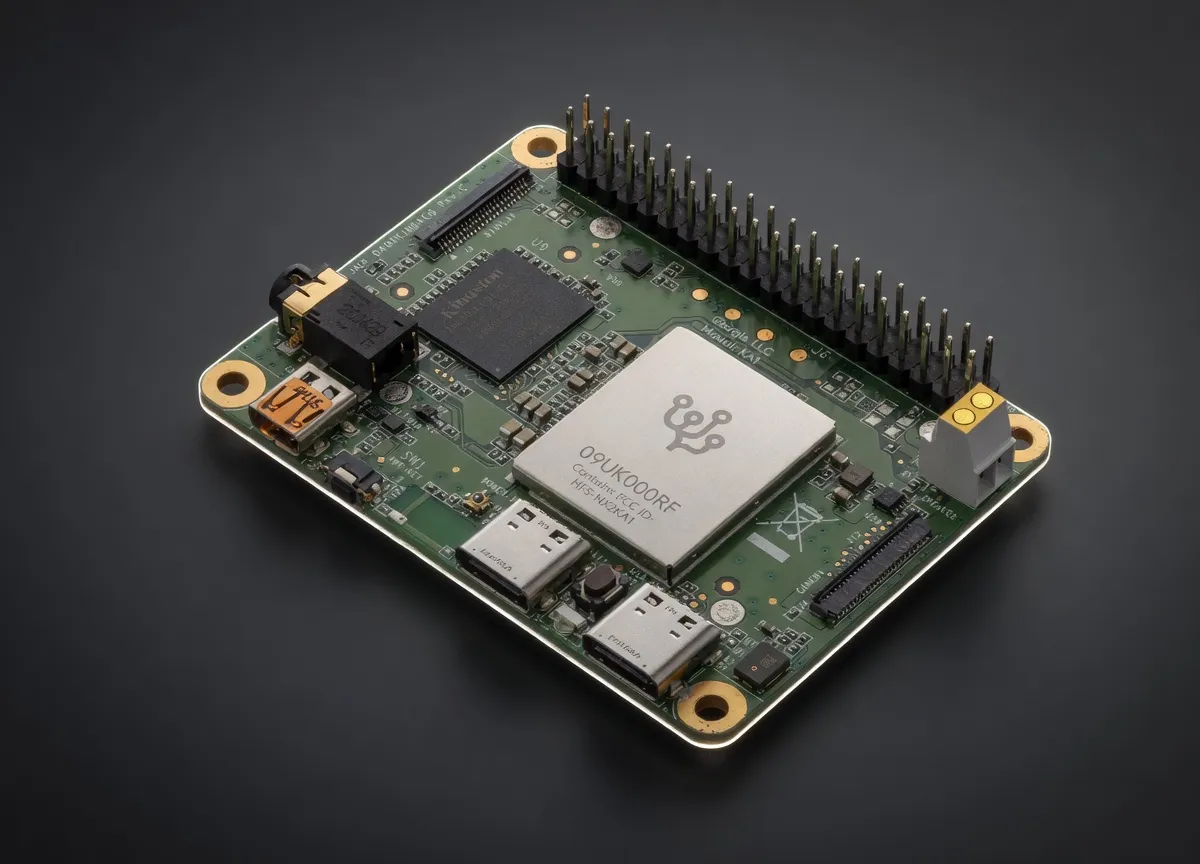
MINIX T5000 has 128 GB of VRAM, enough to run 315 of the 374 open models we track at 4-bit. The largest that still fits well is Falcon 180B (180B), and the top-rated is Nemotron 3.5 Bolt 74B-A9B 24GB at about 37 tok/s.
315 of 374 models run comfortably on MINIX T5000.
See full MINIX T5000 specs and pricingThe top models this device can run at 4-bit, ranked by fit and speed.
| Model | Grade | Speed | VRAM |
|---|---|---|---|
| Nemotron 3.5 Bolt 74B-A9B 24GBNVIDIA | SS | 36.5 tok/s | 43.7 GB |
| NVIDIA Nemotron 3.5 Bolt 74B-A9B 24GBNVIDIA | SS | 36.5 tok/s | 43.7 GB |
| Qwen3-30B-A3BAlibaba | SS | 40.8 tok/s | 21.0 GB |
| Holo4-35B-A3BHcompany | SS | 94.0 tok/s | 20.9 GB |
| Nemotron 3.5 LightningNvidia | SS | 94.0 tok/s | 18.0 GB |
| LFM2.5-24B-A2BLiquid AI | SS | 48.9 tok/s | 17.0 GB |
| Mellum2.1JetBrains | AA | 108.2 tok/s | 7.5 GB |
| AliceAI-Foundation-80B-A3B-Baseyandex | AA | 25.8 tok/s | 53.9 GB |
| LFM2.5-8B-A1BLiquid AI | AA | 75.6 tok/s | 6.8 GB |
| ALoDLM-8BAmazon | AA | 40.7 tok/s | 5.4 GB |
| Apertus 8BEPFL, ETH Zurich, CSCS | AA | 40.7 tok/s | 5.4 GB |
| Recursive FlintRecursive | AA | 30.6 tok/s | 28.8 GB |
| 74B(9B active) | SS | 36.5 tok/s | 43.7 GB | ||
| 74B(9B active) | SS | 36.5 tok/s | 43.7 GB | ||
Qwen3-30B-A3BAlibaba | 30B(3B active) | SS | 40.8 tok/s | 21.0 GB | |
Holo4-35B-A3BHcompany | 35B(3B active) | SS | 94.0 tok/s | 20.9 GB | |
Nemotron 3.5 LightningNvidia | 30B(3B active) | SS | 94.0 tok/s | 18.0 GB | |
LFM2.5-24B-A2BLiquid AI | 24B(2.45B active) | SS | 48.9 tok/s | 17.0 GB | |
Mellum2.1JetBrains | 12B(2.5B active) | AA | 108.2 tok/s | 7.5 GB | |
| 81.29B(3B active) | AA | 25.8 tok/s | 53.9 GB | ||
Ad Tools for AI BuildersAll the hardware and tools you need to run private AI at your office or at home.Shop Now | |||||
LFM2.5-8B-A1BLiquid AI | 8.3B(1.5B active) | AA | 75.6 tok/s | 6.8 GB | |
ALoDLM-8BAmazon | 8B | AA | 40.7 tok/s | 5.4 GB | |
Apertus 8BEPFL, ETH Zurich, CSCS | 8B | AA | 40.7 tok/s | 5.4 GB | |
Recursive FlintRecursive | 39.8B(2.5B active) | AA | 30.6 tok/s | 28.8 GB | |
| 8B | AA | 38.8 tok/s | 5.7 GB | ||
Comet 60BMultiverse Computing | 61.1B(12.8B active) | AA | 26.3 tok/s | 36.4 GB | |
LensVLM-9BApple | 9B | AA | 36.5 tok/s | 6.0 GB | |
| 9B | AA | 36.5 tok/s | 6.0 GB | ||
Ad Vast.aiAffordable on-demand GPU rentals for training and inference. Pick from thousands of hosts.Rent a GPU | |||||
PersonaPlex 7BNVIDIA | 7B | AA | 45.9 tok/s | 4.8 GB | |
Llama 2 7B ChatMeta | 7B | AA | 45.9 tok/s | 4.8 GB | |
Qwen3.6 35B-A3BAlibaba | 35B(3B active) | AA | 25.8 tok/s | 27.1 GB | |
Qwen3.5-35B-A3BAlibaba | 35B(3B active) | AA | 25.8 tok/s | 27.1 GB | |
MiniCPM-V 4.7 35B-A3Bopenbmb | 35.21B(3B active) | AA | 25.8 tok/s | 27.2 GB | |
North Mini CodeCohere | 30B(3B active) | AA | 26.2 tok/s | 24.0 GB | |
Nemotron 3 Nano OmniNVIDIA | 30B(3B active) | AA | 25.8 tok/s | 24.2 GB | |
MiniCPM-V 4.7 1Bopenbmb | 1.55B | AA | 47.3 tok/s | 4.6 GB | |
| AdTools for AI BuildersAll the hardware and tools you need to run private AI at your office or at home.Shop Now | |||||
LFM3-1.7BLiquid AI | 1.7B | AA | 44.2 tok/s | 5.0 GB | |

Model Compatibility
Use the calculator to weigh this device against any other, model by model, with speed and fit scores.
Straight answers to the questions we hear most often.
Can't find what you're looking for? Book a Discovery Call
Nemotron 3.5 Bolt 74B-A9B 24GB is the highest-rated model that runs on MINIX T5000 at 4-bit, at about 37 tok/s. In total, MINIX T5000 can run 315 of the 374 open models we track.
We size each model at 4-bit (Q4_K_M), add the KV cache for its context length and a fixed runtime overhead, then compare that to this device VRAM. Each model is graded on how comfortably it fits and how fast it should run on this card.
It is an estimate of decode speed in tokens per second at 4-bit, based on this device memory bandwidth and each model size. Real speed depends on your runtime, batch size, and context length, so use it to compare models, not as a hard promise.
Lower-bit quantization shrinks a model so more of them fit. These grades already assume 4-bit, which is the common local default. Going below 4-bit can squeeze a larger model in at some quality cost; going above needs more VRAM and may not fit.
Mixture-of-experts models only activate a fraction of their parameters at a time, so their runtime memory is closer to the active size than the headline size. We score fit on the active parameters, which is why some very large models still fit.