- Services
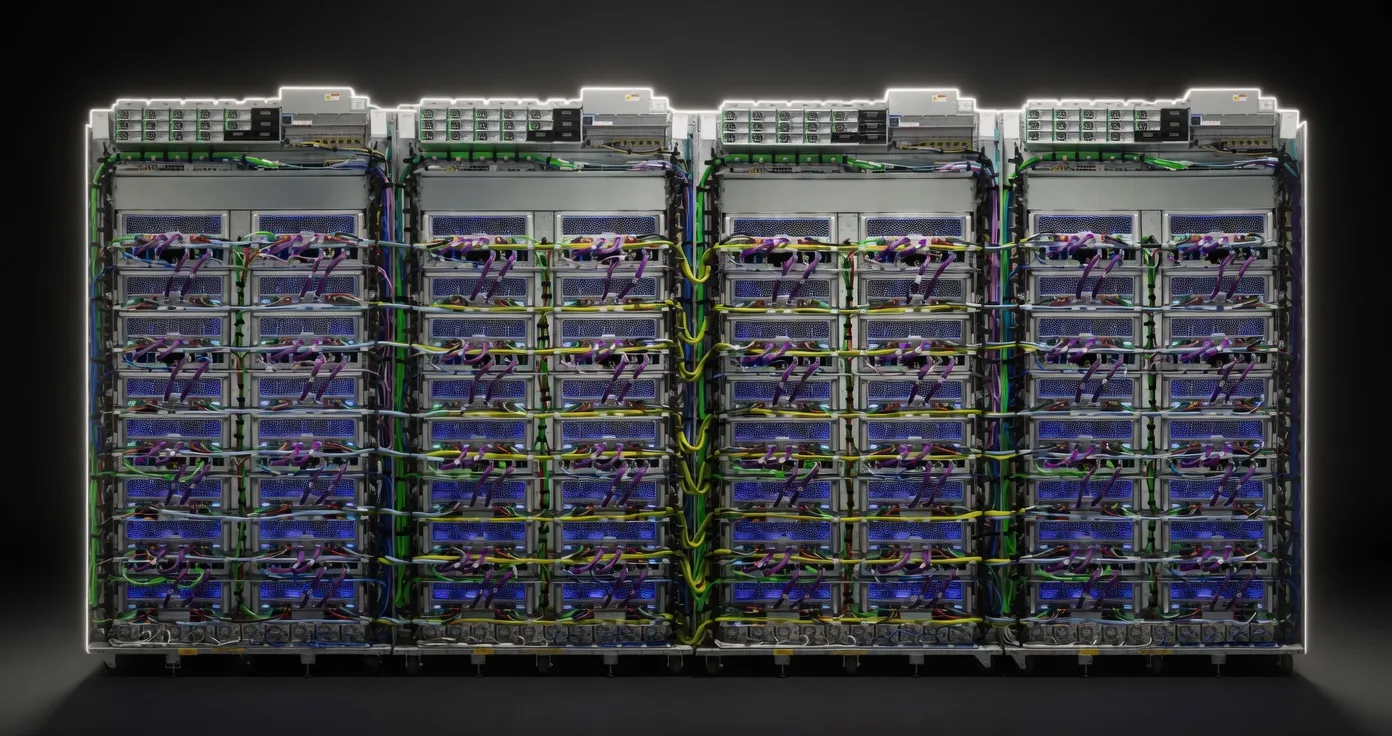
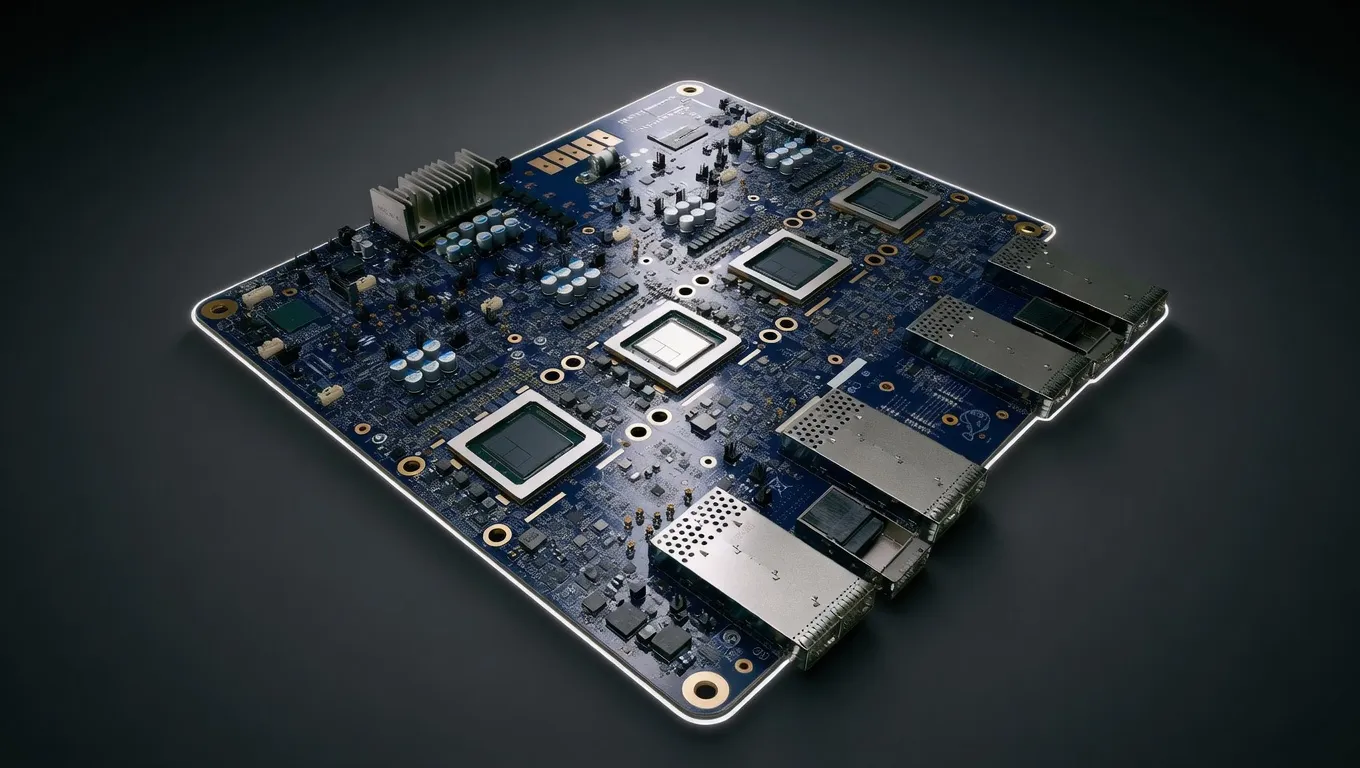
Every open model in our directory, ranked by how well it runs on TPU 8i Max (384GB) at 4-bit. Grades weigh whether the model fits in memory and how fast it should run.
TPU 8i Max has 384 GB of VRAM, enough to run 355 of the 398 open models we track at 4-bit. The largest that still fits well is NorthCUA-Pro 397B (397B), and the top-rated is Mistral Large 2 at about 70 tok/s.
355 of 398 models run comfortably on TPU 8i Max.
See full TPU 8i Max specs and pricingThe top models this device can run at 4-bit, ranked by fit and speed.
| Model | Grade | Speed | VRAM |
|---|---|---|---|
| Mistral Large 2Mistral AI | SS | 70.0 tok/s | 197.8 GB |
| ERNIE 5.5 Flash BaseBaidu | SS | 114.8 tok/s | 274.9 GB |
| DeepSeek-V4-FlashDeepSeek | SS | 123.6 tok/s | 269.2 GB |
| Hunyuan Hy3Tencent | SS | 244.1 tok/s | 215.6 GB |
| Hy3Tencent | SS | 248.6 tok/s | 214.6 GB |
| Naive-N0.5-FlashNaiveAI | SS | 103.7 tok/s | 303.7 GB |
| MiMo-V2.6-Flash-RLXiaomi MiMo | SS | 107.2 tok/s | 300.7 GB |
| IQuest-Q1IQuest | SS | 192.0 tok/s | 249.2 GB |
| GLM-4.5Z.ai | SS | 267.2 tok/s | 239.2 GB |
| GLM-4.6Z.ai | SS | 197.1 tok/s | 257.6 GB |
| GLM-4.7Z.ai | SS | 263.2 tok/s | 241.7 GB |
| NorthCUA-Pro 397BNorthCUA | SS | 1268.3 tok/s | 231.3 GB |
Mistral Large 2Mistral AI | 123B | SS | 70.0 tok/s | 197.8 GB | |
ERNIE 5.5 Flash BaseBaidu | 280B(14B active) | SS | 114.8 tok/s | 274.9 GB | |
DeepSeek-V4-FlashDeepSeek | 284B(13B active) | SS | 123.6 tok/s | 269.2 GB | |
Hunyuan Hy3Tencent | 295B(21B active) | SS | 244.1 tok/s | 215.6 GB | |
Hy3Tencent | 295B(21B active) | SS | 248.6 tok/s | 214.6 GB | |
Naive-N0.5-FlashNaiveAI | 309B(15.5B active) | SS | 103.7 tok/s | 303.7 GB | |
MiMo-V2.6-Flash-RLXiaomi MiMo | 310.76B(15B active) | SS | 107.2 tok/s | 300.7 GB | |
IQuest-Q1IQuest | 320.32B(15B active) | SS | 192.0 tok/s | 249.2 GB | |
Ad Tools for AI BuildersAll the hardware and tools you need to run private AI at your office or at home.Shop Now | |||||
GLM-4.5Z.ai | 355B(32B active) | SS | 267.2 tok/s | 239.2 GB | |
GLM-4.6Z.ai | 355B(32B active) | SS | 197.1 tok/s | 257.6 GB | |
GLM-4.7Z.ai | 358B(32B active) | SS | 263.2 tok/s | 241.7 GB | |
NorthCUA-Pro 397BNorthCUA | 397B(17B active) | SS | 1268.3 tok/s | 231.3 GB | |
Qwen 3.5 OmniAlibaba | 397B(17B active) | SS | 306.5 tok/s | 265.6 GB | |
Qwen3.5-397B-A17BAlibaba | 397B(17B active) | SS | 300.9 tok/s | 266.4 GB | |
| 120B(12B active) | SS | 128.1 tok/s | 170.8 GB | ||
MemT-1.0-FlashMemTensor | 288B(17B active) | SS | 1268.3 tok/s | 168.1 GB | |
Ad Vast.aiAffordable on-demand GPU rentals for training and inference. Pick from thousands of hosts.Rent a GPU | |||||
Nvidia Nemotron 3 SuperNVIDIA | 120B(12B active) | SS | 133.8 tok/s | 166.1 GB | |
Qwen3-235B-A22BAlibaba | 235B(22B active) | SS | 381.1 tok/s | 159.9 GB | |
minimax-m2.5MiniMax | 230B(10B active) | SS | 610.0 tok/s | 150.3 GB | |
Nanbeige4.3-33BNanbeige LLM Lab | 33B | SS | 87.6 tok/s | 158.1 GB | |
| 70B | SS | 122.8 tok/s | 112.8 GB | ||
| 70B | SS | 122.8 tok/s | 112.8 GB | ||
Mixtral 8x22B InstructMistral AI | 141B(39B active) | SS | 317.8 tok/s | 102.7 GB | |
Qwen3.5-122B-A10BAlibaba | 122B(10B active) | SS | 507.7 tok/s | 92.2 GB | |
| AdTools for AI BuildersAll the hardware and tools you need to run private AI at your office or at home.Shop Now | |||||
KolibriAleph Alpha | 78B(3B active) | SS | 527.7 tok/s | 69.7 GB | |

Model Compatibility
Use the calculator to weigh this device against any other, model by model, with speed and fit scores.
Straight answers to the questions we hear most often.
Can't find what you're looking for? Book a Discovery Call
Mistral Large 2 is the highest-rated model that runs on TPU 8i Max at 4-bit, at about 70 tok/s. In total, TPU 8i Max can run 355 of the 398 open models we track.
We size each model at 4-bit (Q4_K_M), add the KV cache for its context length and a fixed runtime overhead, then compare that to this device VRAM. Each model is graded on how comfortably it fits and how fast it should run on this card.
It is an estimate of decode speed in tokens per second at 4-bit, based on this device memory bandwidth and each model size. Real speed depends on your runtime, batch size, and context length, so use it to compare models, not as a hard promise.
Lower-bit quantization shrinks a model so more of them fit. These grades already assume 4-bit, which is the common local default. Going below 4-bit can squeeze a larger model in at some quality cost; going above needs more VRAM and may not fit.
Mixture-of-experts models only activate a fraction of their parameters at a time, so their runtime memory is closer to the active size than the headline size. We score fit on the active parameters, which is why some very large models still fit.