- Services
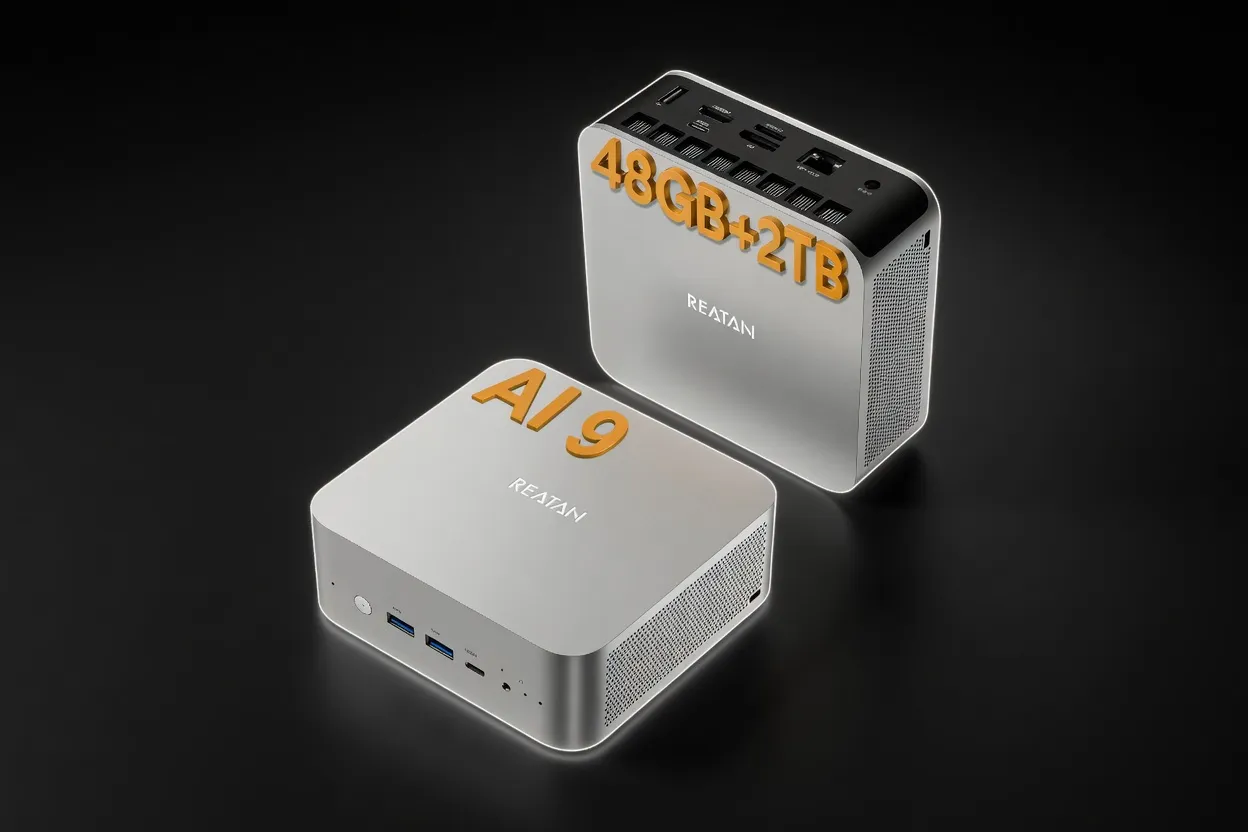
Every open model in our directory, ranked by how well it runs on UniBox AI495 Pro (160GB) at 4-bit. Grades weigh whether the model fits in memory and how fast it should run.
UniBox AI495 Pro has 160 GB of VRAM, enough to run 236 of the 249 open models we track at 4-bit. The largest that still fits well is Kimi K2 Instruct 0905 (1000B), and the top-rated is Qwen3-30B-A3B at about 41 tok/s.
236 of 249 models run comfortably on UniBox AI495 Pro.
See full UniBox AI495 Pro specs and pricingThe top models this device can run at 4-bit, ranked by fit and speed.
| Model | Grade | Speed | VRAM |
|---|---|---|---|
| Qwen3-30B-A3BAlibaba | AA | 40.8 tok/s | 5.4 GB |
| LFM2.5-8B-A1BLiquid AI | AA | 75.6 tok/s | 2.9 GB |
| Llama 3 8B InstructMeta | AA | 38.8 tok/s | 5.7 GB |
| LensVLM-9BApple | AA | 36.5 tok/s | 6.0 GB |
| Carnice-9b for Hermes agentkai-os | AA | 36.5 tok/s | 6.0 GB |
| PersonaPlex 7BNVIDIA | AA | 45.9 tok/s | 4.8 GB |
| Llama 2 7B ChatMeta | AA | 45.9 tok/s | 4.8 GB |
| AliceAI-Foundation-80B-A3B-Baseyandex | AA | 25.8 tok/s | 8.5 GB |
| MiniCPM5-2Bopenbmb | AA | 47.7 tok/s | 4.6 GB |
| LFM2.5-2.6BLiquid AI | AA | 45.0 tok/s | 4.9 GB |
| Gemma 4 E2B ITGoogle | AA | 59.3 tok/s | 3.7 GB |
| VibeThinker-3BWeiboAI | AA | 57.6 tok/s | 3.8 GB |
Qwen3-30B-A3BAlibaba | 30B(3B active) | AA | 40.8 tok/s | 5.4 GB | |
LFM2.5-8B-A1BLiquid AI | 8.3B(1.5B active) | AA | 75.6 tok/s | 2.9 GB | |
| 8B | AA | 38.8 tok/s | 5.7 GB | ||
LensVLM-9BApple | 9B | AA | 36.5 tok/s | 6.0 GB | |
| 9B | AA | 36.5 tok/s | 6.0 GB | ||
PersonaPlex 7BNVIDIA | 7B | AA | 45.9 tok/s | 4.8 GB | |
Llama 2 7B ChatMeta | 7B | AA | 45.9 tok/s | 4.8 GB | |
| 81.29B(3B active) | AA | 25.8 tok/s | 8.5 GB | ||
Ad Tools for AI BuildersAll the hardware and tools you need to run private AI at your office or at home.Shop Now | |||||
MiniCPM5-2Bopenbmb | 2.52B | AA | 47.7 tok/s | 4.6 GB | |
LFM2.5-2.6BLiquid AI | 2.69B | AA | 45.0 tok/s | 4.9 GB | |
Gemma 4 E2B ITGoogle | 2B | AA | 59.3 tok/s | 3.7 GB | |
VibeThinker-3BWeiboAI | 3B | AA | 57.6 tok/s | 3.8 GB | |
North Mini CodeCohere | 30B(3B active) | AA | 26.2 tok/s | 8.4 GB | |
Mistral 7B InstructMistral AI | 7B | AA | 34.4 tok/s | 6.4 GB | |
Nemotron 3 Nano OmniNVIDIA | 30B(3B active) | AA | 25.8 tok/s | 8.5 GB | |
Qwen3.6 35B-A3BAlibaba | 35B(3B active) | AA | 25.8 tok/s | 8.5 GB | |
Ad Vast.aiAffordable on-demand GPU rentals for training and inference. Pick from thousands of hosts.Rent a GPU | |||||
Qwen3.5-35B-A3BAlibaba | 35B(3B active) | AA | 25.8 tok/s | 8.5 GB | |
Llama 2 13B ChatMeta | 13B | AA | 26.0 tok/s | 8.5 GB | |
Gemma 4 E4B ITGoogle | 4B | AA | 31.8 tok/s | 6.9 GB | |
Gemma 3 4B ITGoogle | 4B | AA | 31.8 tok/s | 6.9 GB | |
Mixtral 8x7B InstructMistral AI | 46.7B(12.9B active) | BB | 19.3 tok/s | 11.4 GB | |
DiffusionGemma 26B-A4BGoogle | 25.2B(3.8B active) | BB | 21.0 tok/s | 10.5 GB | |
Gemma 4 26B-A4B ITGoogle | 26B(4B active) | BB | 20.0 tok/s | 11.0 GB | |
Xing4.0-29B-A4BChina Telecom AI | 29B(4B active) | BB | 19.6 tok/s | 11.2 GB | |
| AdTools for AI BuildersAll the hardware and tools you need to run private AI at your office or at home.Shop Now | |||||
Kimi K2 Instruct 0905Moonshot AI | 1000B(32B active) | BB | 2.6 tok/s | 84.6 GB | |
Model Compatibility
Use the calculator to weigh this device against any other, model by model, with speed and fit scores.
Straight answers to the questions we hear most often.
Can't find what you're looking for? Book a Discovery Call
Qwen3-30B-A3B is the highest-rated model that runs on UniBox AI495 Pro at 4-bit, at about 41 tok/s. In total, UniBox AI495 Pro can run 236 of the 249 open models we track.
We size each model at 4-bit (Q4_K_M), add the KV cache for its context length and a fixed runtime overhead, then compare that to this device VRAM. Each model is graded on how comfortably it fits and how fast it should run on this card.
It is an estimate of decode speed in tokens per second at 4-bit, based on this device memory bandwidth and each model size. Real speed depends on your runtime, batch size, and context length, so use it to compare models, not as a hard promise.
Lower-bit quantization shrinks a model so more of them fit. These grades already assume 4-bit, which is the common local default. Going below 4-bit can squeeze a larger model in at some quality cost; going above needs more VRAM and may not fit.
Mixture-of-experts models only activate a fraction of their parameters at a time, so their runtime memory is closer to the active size than the headline size. We score fit on the active parameters, which is why some very large models still fit.