- Services
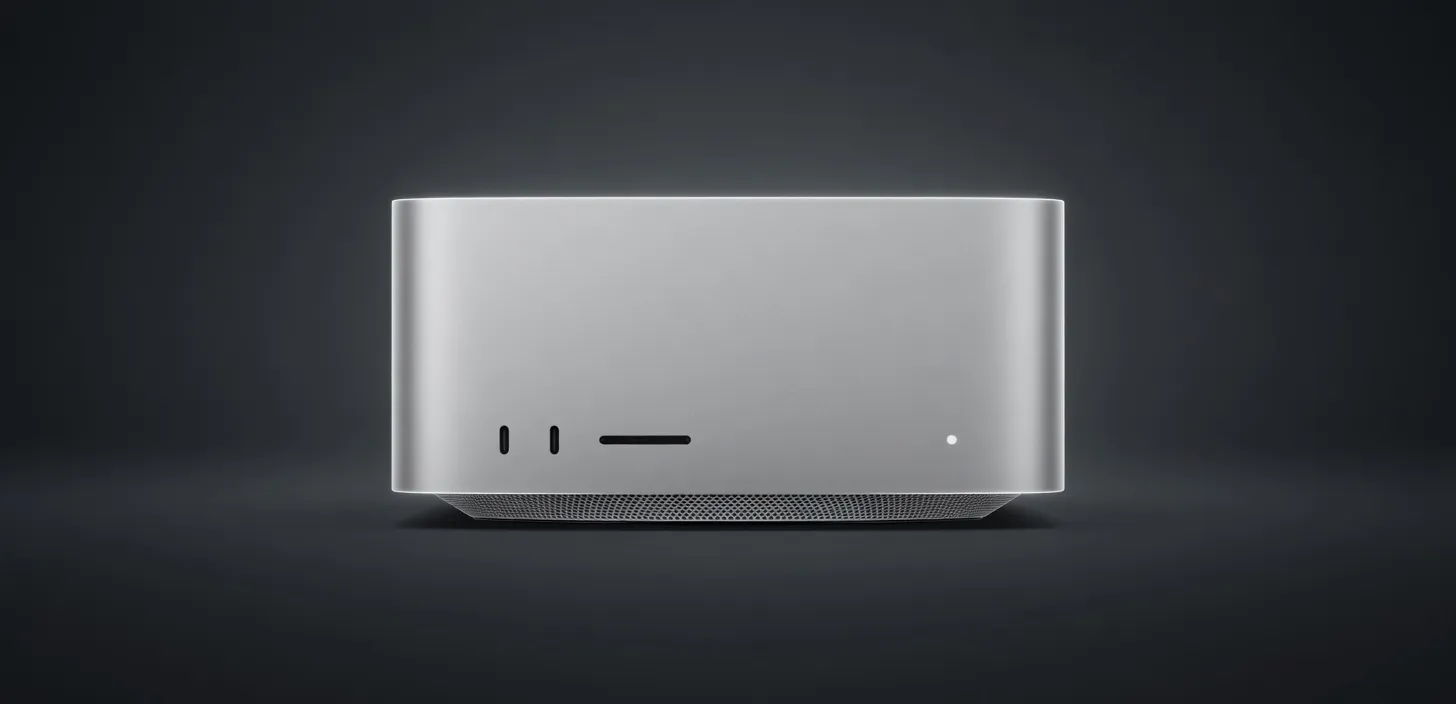
Every open model in our directory, ranked by how well it runs on Mac Studio with M5 Ultra (512GB) at 4-bit. Grades weigh whether the model fits in memory and how fast it should run.
Mac Studio with M5 Ultra has 512 GB of VRAM, enough to run 261 of the 267 open models we track at 4-bit. The largest that still fits well is LongCat-2.0 (1600B), and the top-rated is minimax-m2.5 at about 43 tok/s.
261 of 267 models run comfortably on Mac Studio with M5 Ultra.
See full Mac Studio with M5 Ultra specs and pricingThe top models this device can run at 4-bit, ranked by fit and speed.
| Model | Grade | Speed | VRAM |
|---|---|---|---|
| minimax-m2.5MiniMax | SS | 42.6 tok/s | 22.7 GB |
| Mixtral 8x7B InstructMistral AI | SS | 85.0 tok/s | 11.4 GB |
| AliceAI-Foundation-80B-A3B-Baseyandex | SS | 113.2 tok/s | 8.5 GB |
| K2-Horizon-MoVA-36B-A4BInstitute of Foundation Models | AA | 49.3 tok/s | 19.6 GB |
| Holo4-27BHcompany | AA | 56.7 tok/s | 17.0 GB |
| DiffusionGemma 26B-A4BGoogle | AA | 92.1 tok/s | 10.5 GB |
| Gemma 4 26B-A4B ITGoogle | AA | 87.7 tok/s | 11.0 GB |
| Xing4.0-29B-A4BChina Telecom AI | AA | 86.2 tok/s | 11.2 GB |
| North Mini CodeCohere | AA | 115.2 tok/s | 8.4 GB |
| Nemotron 3 Nano OmniNVIDIA | AA | 113.2 tok/s | 8.5 GB |
| Qwen3.6 35B-A3BAlibaba | AA | 113.2 tok/s | 8.5 GB |
| Qwen3.5-35B-A3BAlibaba | AA | 113.2 tok/s | 8.5 GB |
minimax-m2.5MiniMax | 230B(10B active) | SS | 42.6 tok/s | 22.7 GB | |
Mixtral 8x7B InstructMistral AI | 46.7B(12.9B active) | SS | 85.0 tok/s | 11.4 GB | |
| 81.29B(3B active) | SS | 113.2 tok/s | 8.5 GB | ||
K2-Horizon-MoVA-36B-A4BInstitute of Foundation Models | 36B(4B active) | AA | 49.3 tok/s | 19.6 GB | |
Holo4-27BHcompany | 27B | AA | 56.7 tok/s | 17.0 GB | |
DiffusionGemma 26B-A4BGoogle | 25.2B(3.8B active) | AA | 92.1 tok/s | 10.5 GB | |
Gemma 4 26B-A4B ITGoogle | 26B(4B active) | AA | 87.7 tok/s | 11.0 GB | |
Xing4.0-29B-A4BChina Telecom AI | 29B(4B active) | AA | 86.2 tok/s | 11.2 GB | |
Ad Tools for AI BuildersAll the hardware and tools you need to run private AI at your office or at home.Shop Now | |||||
North Mini CodeCohere | 30B(3B active) | AA | 115.2 tok/s | 8.4 GB | |
Nemotron 3 Nano OmniNVIDIA | 30B(3B active) | AA | 113.2 tok/s | 8.5 GB | |
Qwen3.6 35B-A3BAlibaba | 35B(3B active) | AA | 113.2 tok/s | 8.5 GB | |
Qwen3.5-35B-A3BAlibaba | 35B(3B active) | AA | 113.2 tok/s | 8.5 GB | |
Qwen3-30B-A3BAlibaba | 30B(3B active) | AA | 179.4 tok/s | 5.4 GB | |
Holo4-35B-A3BHcompany | 35B(3B active) | AA | 413.1 tok/s | 2.3 GB | |
KolibriAleph Alpha | 78B(3B active) | AA | 36.8 tok/s | 26.2 GB | |
Qwen3.5-122B-A10BAlibaba | 122B(10B active) | AA | 35.4 tok/s | 27.3 GB | |
Ad Vast.aiAffordable on-demand GPU rentals for training and inference. Pick from thousands of hosts.Rent a GPU | |||||
Llama 2 13B ChatMeta | 13B | AA | 114.1 tok/s | 8.5 GB | |
Falcon 40B InstructTechnology Innovation Institute | 40B | AA | 39.7 tok/s | 24.4 GB | |
| 8B | AA | 72.5 tok/s | 13.3 GB | ||
Qwen3.5-9BAlibaba | 9B | AA | 39.3 tok/s | 24.6 GB | |
Apertus 8BEPFL, ETH Zurich, CSCS | 8B | AA | 178.8 tok/s | 5.4 GB | |
| 8B | AA | 170.5 tok/s | 5.7 GB | ||
LensVLM-9BApple | 9B | AA | 160.6 tok/s | 6.0 GB | |
| 9B | AA | 160.6 tok/s | 6.0 GB | ||
| AdTools for AI BuildersAll the hardware and tools you need to run private AI at your office or at home.Shop Now | |||||
LFM2.5-8B-A1BLiquid AI | 8.3B(1.5B active) | AA | 332.4 tok/s | 2.9 GB | |

Model Compatibility
Use the calculator to weigh this device against any other, model by model, with speed and fit scores.
Straight answers to the questions we hear most often.
Can't find what you're looking for? Book a Discovery Call
minimax-m2.5 is the highest-rated model that runs on Mac Studio with M5 Ultra at 4-bit, at about 43 tok/s. In total, Mac Studio with M5 Ultra can run 261 of the 267 open models we track.
We size each model at 4-bit (Q4_K_M), add the KV cache for its context length and a fixed runtime overhead, then compare that to this device VRAM. Each model is graded on how comfortably it fits and how fast it should run on this card.
It is an estimate of decode speed in tokens per second at 4-bit, based on this device memory bandwidth and each model size. Real speed depends on your runtime, batch size, and context length, so use it to compare models, not as a hard promise.
Lower-bit quantization shrinks a model so more of them fit. These grades already assume 4-bit, which is the common local default. Going below 4-bit can squeeze a larger model in at some quality cost; going above needs more VRAM and may not fit.
Mixture-of-experts models only activate a fraction of their parameters at a time, so their runtime memory is closer to the active size than the headline size. We score fit on the active parameters, which is why some very large models still fit.